GroqCloud Free Tier: Technical Reference Guide
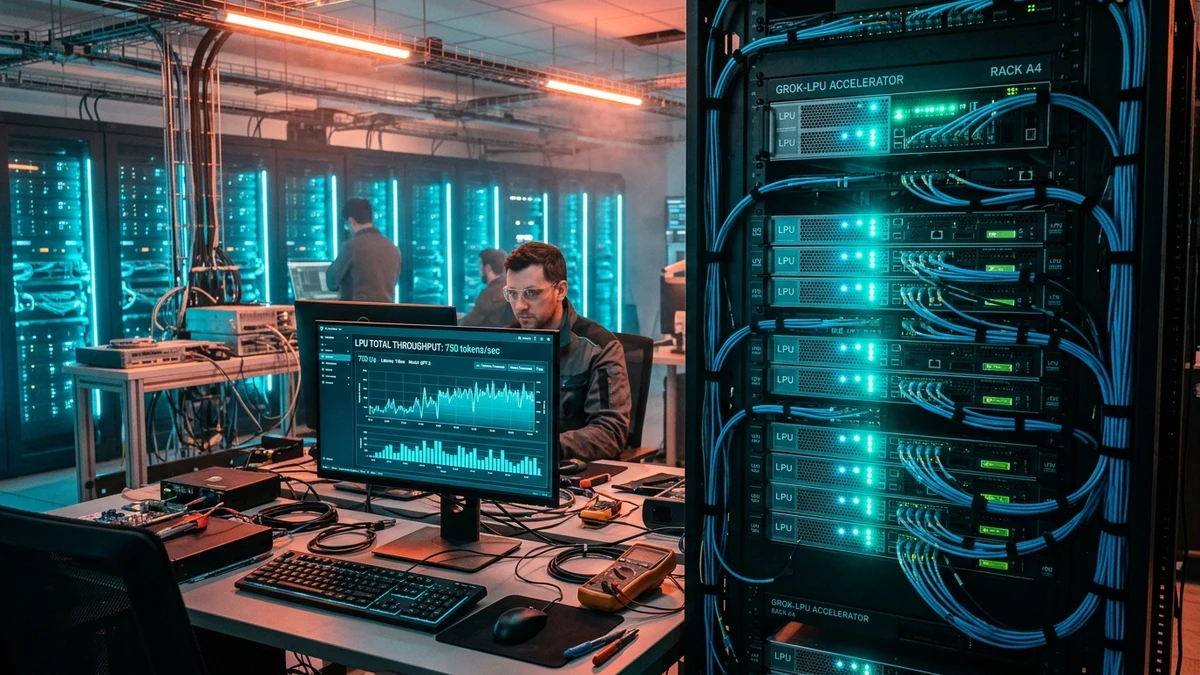
GroqCloud offers free developer inference powered by custom Language Processing Units (LPUs). Free tier accounts receive up to 30 requests per minute and 14,400 daily requests with sub-150ms Time to First Token and generation speeds exceeding 700 tokens per second.
Groq LPU Throughput & Latency Engine
 ✓
1. GroqCloud Free Tier Rate Limit Envelopes & Quotas
Unlike conventional GPU cloud hosting environments where queuing overhead and memory bandwidth contention introduce unpredictable response delays, Groq's bespoke Tensor Streaming Processor (LPU) architecture delivers deterministic token generation. Under the official GroqCloud developer free tier, software engineers receive access to generous Requests Per Minute (RPM) and Tokens Per Minute (TPM) envelopes across frontier open-weight models.
Each registered developer account is provisioned with an API key permitting up to thirty requests per minute on primary endpoints and a massive ceiling of 14,400 requests per day on lightweight models such as Llama 3.1 8B Instant. This allocation allows development teams to build real-time developer assistants, semantic search re-rankers, and automated code reviewers without spending a single dollar on cloud compute.
| Model Variant | Model Identifier | RPM Limit | TPM Allowance | RPD Ceiling | Output Speed |
|---|---|---|---|---|---|
| Llama 3.3 70B Versatile | llama-3.3-70b-versatile | 30 RPM | 6,000 TPM | 1,000 RPD | 280 tok/s |
| Llama 3.1 8B Instant | llama-3.1-8b-instant | 30 RPM | 20,000 TPM | 14,400 RPD | 750 tok/s |
| Mixtral 8x7B 32k | mixtral-8x7b-32768 | 30 RPM | 5,000 TPM | 1,000 RPD | 480 tok/s |
| Gemma 2 9B IT | gemma2-9b-it | 30 RPM | 15,000 TPM | 14,400 RPD | 420 tok/s |
2. Sub-150ms Latency & Real-Time Interaction Optimization
In interactive user interfaces, conversational voice pipelines, and multi-agent reasoning chains, latency is the defining parameter of user experience. Traditional high-end GPUs (such as NVIDIA A100 or H100 clusters) frequently exhibit Time to First Token (TTFT) intervals exceeding 600ms due to CUDA kernel compilation delays, KV-cache loading times, and memory bus latency.
By executing models on ultra-fast Static Random-Access Memory (SRAM) interconnected across LPUs, Groq compresses TTFT to between 110ms and 140ms. Sustained streaming throughput reaches up to 750 tokens per second on Llama 3.1 8B and 280 tokens per second on Llama 3.3 70B. For software architects building iterative multi-step agentic loops—where one model's output feeds directly into a second model for verification—this speed advantage compresses thirty-second workflows into three seconds of total execution time.
3. OpenAI Client Integration & Code Execution Snippets
Transitioning existing applications from OpenAI or other cloud APIs to Groq requires modifying only the endpoint URL and API key. Groq provides total drop-in compatibility with the OpenAI SDK specification, allowing developers to retain existing parameter definitions, streaming handlers, and function-calling schemas without writing custom parsers.
Inspect the production-ready integration examples below for cURL command-line scripts, Python backend services, and TypeScript web applications:
curl https://openrouter.ai/api/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $OPENROUTER_API_KEY" \
  -d '{
    "model": "meta-llama/llama-3.3-70b-instruct:free",
    "messages": [
      {"role": "user", "content": "Hello, how do I optimize free API token quotas?"}
    ]
  }'
from openai import OpenAI
client = OpenAI(
base_url="https://openrouter.ai/api/v1",
api_key="your_api_key_here",
)
response = client.chat.completions.create(
model="meta-llama/llama-3.3-70b-instruct:free",
messages=[
{"role": "user", "content": "Hello, how do I optimize free API token quotas?"}
],
)
print(response.choices[0].message.content)import OpenAI from "openai";
const openai = new OpenAI({
baseURL: "https://openrouter.ai/api/v1",
apiKey: "your_api_key_here",
});
async function main() {
const completion = await openai.chat.completions.create({
model: "meta-llama/llama-3.3-70b-instruct:free",
messages: [
{ role: "user", content: "Hello, how do I optimize free API token quotas?" }
],
});
console.log(completion.choices[0].message.content);
}
main();4. Enterprise Scaling, Quota Exhaustion & Commercial Migration
When scaling beyond the free tier's 30 RPM boundary, Groq provides an on-demand commercial tier featuring usage-based billing at transparent per-million token rates. Applications approaching daily limits can implement multi-provider fallbacks: routing routine conversational requests through Groq's high-speed free tier, while gracefully diverting burst traffic to secondary free endpoints such as Google AI Studio or OpenRouter during unexpected volume spikes.