Gemini API Free Tier Limits & Quotas Breakdown
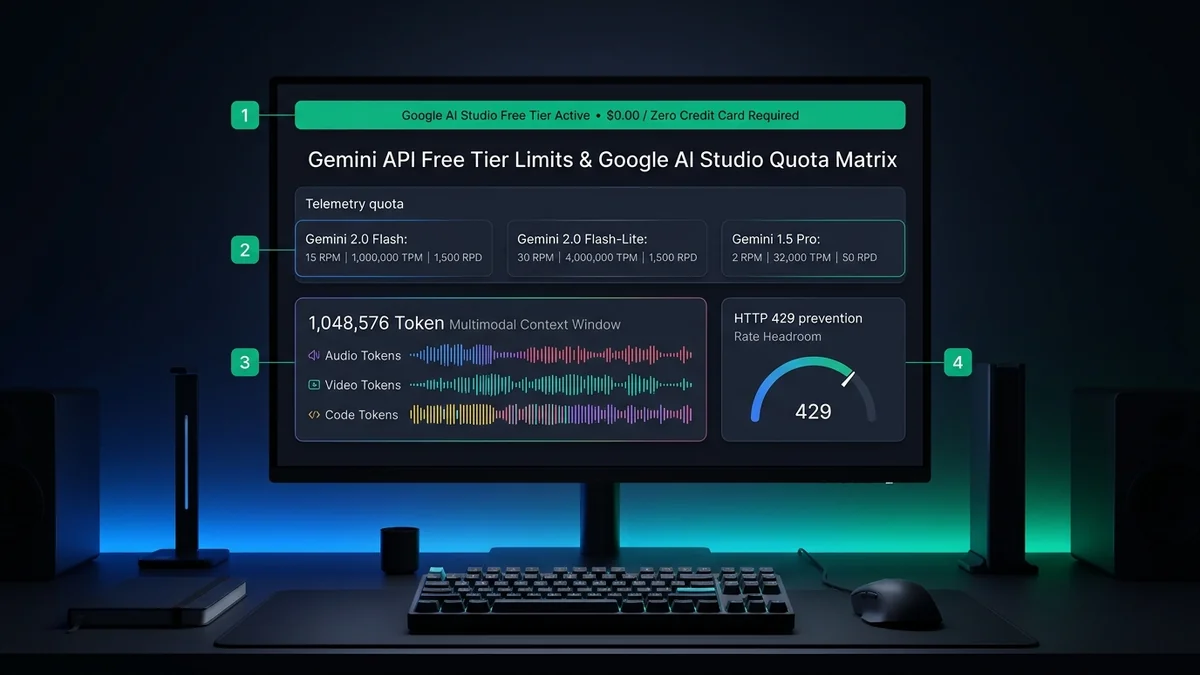
Direct Answer: Google AI Studio provides 100% free developer API keys granting access to Gemini 2.0 Flash at 15 Requests Per Minute (RPM), 1,000,000 Tokens Per Minute (TPM), and 1,500 Requests Per Day (RPD), while Gemini 2.0 Flash-Lite increases throughput to 30 RPM and 4,000,000 TPM. For deep analytical reasoning, Gemini 1.5 Pro provides 2 RPM, 32,000 TPM, and 50 RPD with up to 2,097,152 context tokens. All free tier quotas operate without credit card verification, refresh on a rolling 24-hour midnight UTC schedule, and return HTTP 429 RESOURCE_EXHAUSTED when capacity thresholds are reached.
Gemini API Free Tier Rate Limit & Concurrency Engine
 ✓
1. Verified Gemini API Free Tier Quota Matrix Across Models (2026)
Google AI Studio serves as Google's primary playground and direct developer gateway, separating free prototyping workloads from complex Google Cloud Platform (GCP) billing setups. Under the free tier, developers receive dedicated foundation model access with zero upfront fees, zero billing minimums, and zero credit card requirements.
For developers requiring active free compute, see the Google AI Studio setup roadmap and free AI credits directory indexed above. Compare the official production quotas enforced on free API keys below:
| Model Variant | API Identifier | RPM Cap | TPM Limit | Daily Quota (RPD) | Max Context | Billing Policy |
|---|---|---|---|---|---|---|
| Gemini 2.0 Flash | gemini-2.0-flash | 15 RPM | 1,000,000 TPM | 1,500 RPD | 1,048,576 tokens | Zero Credit Card ($0.00) |
| Gemini 2.0 Flash-Lite | gemini-2.0-flash-lite | 30 RPM | 4,000,000 TPM | 1,500 RPD | 1,048,576 tokens | Zero Credit Card ($0.00) |
| Gemini 1.5 Flash | gemini-1.5-flash | 15 RPM | 1,000,000 TPM | 1,500 RPD | 1,048,576 tokens | Zero Credit Card ($0.00) |
| Gemini 1.5 Pro | gemini-1.5-pro | 2 RPM | 32,000 TPM | 50 RPD | 2,097,152 tokens | Zero Credit Card ($0.00) |
| Gemma 2 (27B IT) | gemma-2-27b-it | 30 RPM | 150,000 TPM | 1,500 RPD | 8,192 tokens | Zero Credit Card ($0.00) |
2. Understanding the 3-Axis Throttling Engine: RPM vs TPM vs RPD
Google's API gateway regulates free tier traffic across three concurrent dimensions. Exceeding any single parameter immediately triggers an HTTP 429 status code with the payload error RESOURCE_EXHAUSTED:
- Requests Per Minute (RPM — Sliding 60-Second Window): Regulates server connection concurrency. For Gemini 2.0 Flash (15 RPM), requests must be spaced by an average interval of at least 4,000 milliseconds. Rapid burst transmissions of 5 requests within 2 seconds will trigger an immediate temporary 429 block even if total minute volume remains low.
- Tokens Per Minute (TPM — Input Prompt + Output Generation): Regulates computational processing load. Tokens count both the incoming prompt payload (text, codebase files, multimodal audio/video frames) and the generated candidate output. On Gemini 2.0 Flash-Lite, the 4,000,000 TPM ceiling accommodates high-density batch data transformations.
- Requests Per Day (RPD — Rolling 24-Hour Reset at Midnight UTC): Sets a hard ceiling on cumulative daily invocations. On Flash models, 1,500 daily requests allow sustained automation (up to 62.5 requests per hour around the clock). Once your daily RPD pool is depleted, further calls fail until midnight UTC (16:00 PST).
3. Architecture: HTTP 429 Error Handling & Exponential Backoff Failover
Production-grade systems using Google AI Studio free tier keys should implement resilient client-side exponential backoff with jitter and automated multi-provider fallback:
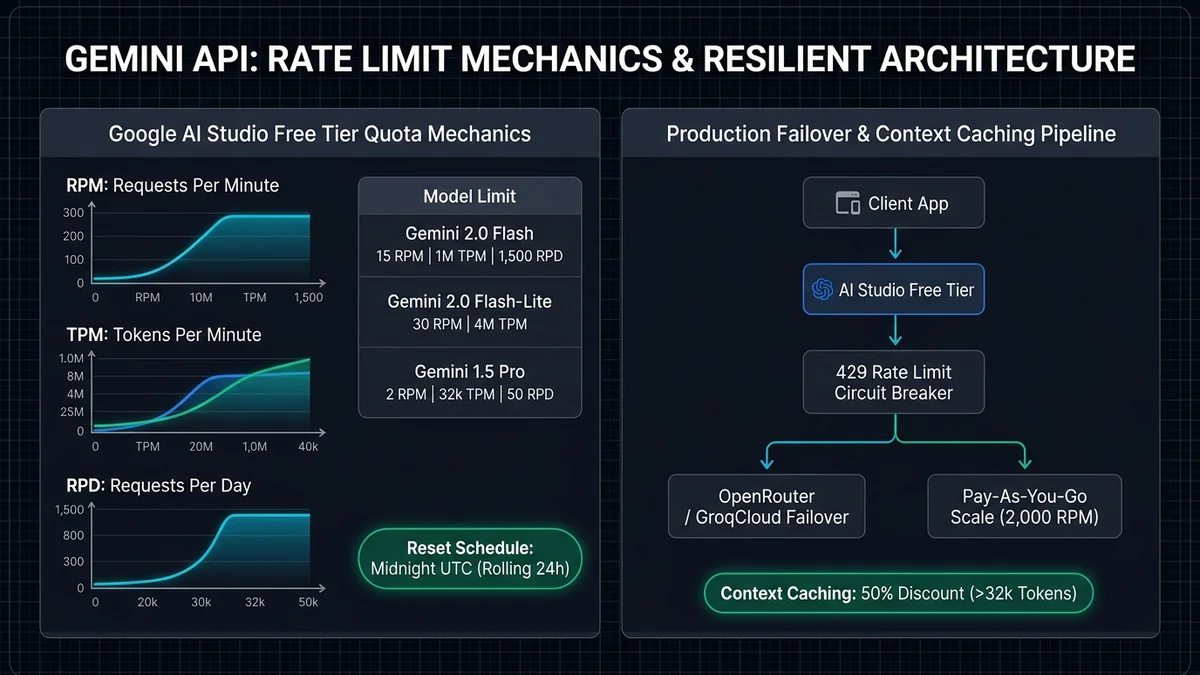
- Exponential Backoff with Full Jitter: When receiving an HTTP 429 response, wait
t = min(max_backoff, base * 2^attempt) + random_jitterbefore retrying. Google's rate limiter clears sliding-window bursts within 2 to 5 seconds. - Secondary Router Failover: When daily RPD quotas (1,500 requests) are exhausted, automatically redirect requests to OpenRouter's 20 RPM free models or GroqCloud's 30 RPM inference engine without disrupting end-user workflows.
- Prompt Context Truncation: For long-context repositories or document audits, trim unneeded historical turns to remain within the 1M-token window and keep TPM consumption well below the 1,000,000 token ceiling.
4. Free Tier vs Pay-As-You-Go Scaling & Context Caching Economics
When scaling an application beyond prototyping thresholds, transitioning to Google AI Studio's Pay-As-You-Go tier unlocks massive throughput advantages while maintaining cost efficiency:
- Throughput Escalation: Upgrading to paid billing increases Gemini 2.0 Flash concurrency from 15 RPM to 2,000 RPM and 4,000,000 TPM, eliminating daily RPD caps completely.
- Automatic 50% Context Caching Discount: On payloads exceeding 32,768 tokens (such as large codebase architectures or legal corpora), Google AI Studio caches input context in memory. Cached tokens receive an automatic 50% discount on input billing ($0.05 per 1M tokens vs $0.10 standard).
- Data Privacy Guarantees: On the Free Tier, Google may use prompt and output data to improve Google products pursuant to their Terms of Service. Upgrading to Pay-As-You-Go guarantees enterprise data isolation—customer prompts and generated tokens are never used for model retraining.
5. Complementary Free Developer API Tiers & Compute Hubs
Combine your Gemini API free keys with other verified zero-cost developer gateways across the ecosystem:
Step-by-step API key issuance, system prompts, and Python SDK integration guide.
10M Free Tokens DeepSeek API Free Credits →Claim free DeepSeek-V3 and R1 tokens via OpenRouter :free and PPIO serverless vouchers.
560 Tok/s LPU GroqCloud Free Tier (30 RPM) →Ultra-fast LPU inference on Llama 3.3 70B and DeepSeek R1 Distill at 30 RPM free.
Multi-Model Gateway OpenRouter Free Models →Access 15+ curated foundation models with zero credit card via :free endpoint tags.
24GB ARM Forever Oracle Cloud Free Tier ($300 + ARM) →Deploy private Ollama instances on 4 Ampere A1 ARM cores and 24 GB RAM at $0.00/mo.
IDE Economics Antigravity Token Matrix →Compare prompt caching efficiency, token burn rates, and developer savings across AI IDEs.
6. Frequently Asked Questions: Gemini API Free Tier Limits & Quotas
Does the Gemini API free tier require a credit card or billing account?
No. Google AI Studio allows developers to generate API keys and access Gemini 2.0 Flash, Flash-Lite, and 1.5 Pro without binding a credit card, PayPal, or Google Cloud billing account. Access is permanently free within published rate limits.
What happens if I exceed 15 RPM or 1,000,000 TPM on Gemini 2.0 Flash?
When your application breaches the 15 RPM velocity or 1M TPM processing ceiling, Google's API returns an HTTP 429 status code with the error RESOURCE_EXHAUSTED. Implementing exponential backoff with a 2-to-5-second delay resolves temporary burst throttling.
When does the Gemini API free tier daily quota (1,500 RPD) reset?
Daily request quotas (1,500 RPD for Flash models and 50 RPD for Gemini 1.5 Pro) reset on a rolling 24-hour cycle synchronized to Midnight UTC (16:00 PST / 19:00 EST). Once depleted, requests fail with 429 until the reset window opens.
Are prompt inputs and outputs kept private on the Gemini API free tier?
Under the free tier terms of service, Google may utilize human reviewers and automated telemetry to review prompt inputs and outputs to train and refine Google models. For strict enterprise confidentiality, developers can switch to Pay-As-You-Go billing where prompts are never used for model training.