DeepSeek API Free Credits & 10M Token Guide
Direct Answer: Free AI Credits for DeepSeek-V3 (deepseek-chat) and DeepSeek-R1 (deepseek-reasoner) provide up to 16,000,000+ combined free tokens across verified developer gateways: PPIO Serverless issues a ~5,000,000 free DeepSeek token registration voucher, OpenRouter provides permanent $0.00/token access via deepseek/deepseek-r1:free at 20 RPM (200 RPD), NVIDIA NIM offers 40 RPM free prototyping, and Alibaba Cloud Model Studio grants 1,000,000 free tokens per model for 90 days. On native api.deepseek.com endpoints, automatic KV-cache disk prefix matching reduces input costs by 90% to $0.014 per 1M tokens.
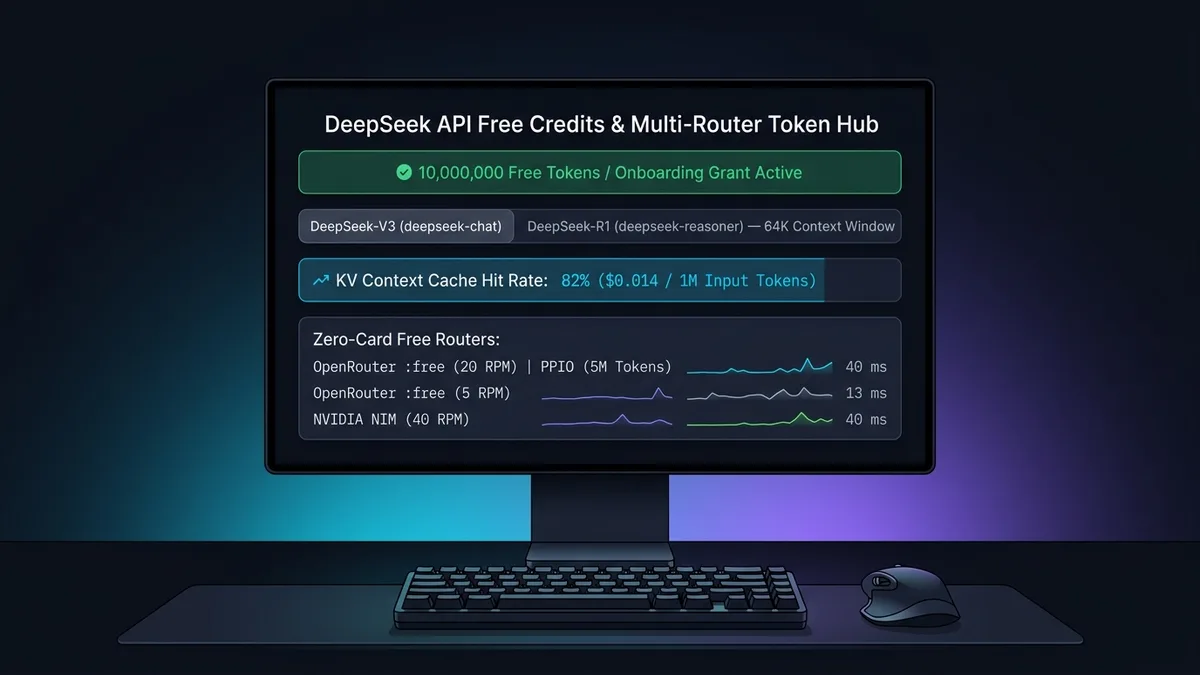
DeepSeek Free Token Grant & Context Cache Sizer
Compare free token capacity across native DeepSeek KV-cache disk pricing ($0.014/1M cached input), PPIO's 5M token registration voucher, OpenRouter :free endpoints (20 RPM), and NVIDIA NIM (40 RPM).
 ✓
1. Where Can Developers Claim Free DeepSeek-V3 & DeepSeek-R1 API Credits in 2026?
Because DeepSeek-V3 (671B total parameters, 37B active per token Mixture-of-Experts) and DeepSeek-R1 release their model weights openly under the MIT License, developers are not restricted to a single congested billing portal. When native platform.deepseek.com onboarding vouchers are paused during peak global traffic bursts, software engineers can aggregate over 16,000,000 free DeepSeek tokens across six verified OpenAI-compatible inference providers.
For developers requiring active free compute, see the PPIO 5M DeepSeek tokens and OpenRouter free model matrix indexed in our master directory above. Compare the exact token allowances, rate limits, and credit card policies across all six providers below:
| Inference Provider / Gateway | Supported DeepSeek Models | Verified Free Allowance | Rate Limits (RPM / RPD) | Credit Card Policy |
|---|---|---|---|---|
| DeepSeek Native Platform (platform.deepseek.com) | deepseek-chat (V3), deepseek-reasoner (R1) | 10M Tokens / ¥10 CNY Promotional Grant | Dynamic Dynamic Concurrency (No RPM Cap) | No Card for Voucher / $2 Min Top-Up |
| OpenRouter :free Gateway (openrouter.ai) | deepseek/deepseek-chat:free, deepseek-r1:free | 100% Free Forever (:free Endpoint Tag) | 20 RPM / 200 RPD (60 RPM w/ $10 Lifetime) | Zero Credit Card Required |
| PPIO Serverless AI Cloud (ppinfra.com) | DeepSeek-V3, DeepSeek-R1 (671B Full Weights) | ~5,000,000 Free DeepSeek Tokens Voucher | 30 RPM / 60,000 TPM Standard Tier | Zero Credit Card on Registration |
| NVIDIA NIM Microservices (build.nvidia.com) | deepseek-ai/deepseek-r1 | 1,000–5,000 Free Prototyping Credits | 40 Requests Per Minute (RPM) | Zero Credit Card (Corporate/Dev Email) |
| Alibaba Cloud Model Studio (Bailian Intl) | deepseek-v3, deepseek-r1, Distill-Qwen-32B | 1,000,000 Free Tokens Per Model (90 Days) | 15–30 RPM (Singapore International Region) | Account Verification Required |
| Fireworks AI Serverless (fireworks.ai) | accounts/fireworks/models/deepseek-v3 & r1 | $1.00 Free Starter Credit (~3.5M Tokens) | 60 RPM High-Speed FP8 Inference | Zero Credit Card for $1 Starter |
2. How to Stack Free DeepSeek API Endpoints with OpenAI SDK Failover
Every provider hosting DeepSeek-V3 and DeepSeek-R1 exposes a drop-in OpenAI-compatible /v1/chat/completions schema. By chaining your free API keys in a client-side fallback array, your application or IDE coding assistant (Cursor, Cline, Roo Code, Continue.dev) achieves uninterrupted zero-cost inference:
- Primary Zero-Card Route (OpenRouter
:free— 20 RPM): Authenticate at OpenRouter with GitHub and route requests tohttps://openrouter.ai/api/v1using model IDdeepseek/deepseek-r1:freeordeepseek/deepseek-chat:free. You receive 20 requests per minute and 200 requests per day at $0.00 with zero credit card required. - Secondary High-Quota Voucher (PPIO Serverless — 5,000,000 Free Tokens): Register a developer account on PPIO to claim the new-user registration voucher (~5,000,000 DeepSeek-V3 tokens) with full 64K context support and no upfront card charge.
- Tertiary Low-Latency Hardware Route (NVIDIA NIM — 40 RPM): Generate a free API key on
build.nvidia.comtargetingdeepseek-ai/deepseek-r1. NVIDIA NIM executes on dedicated TensorRT-LLM H100 clusters at up to 40 RPM during your free prototyping allocation. - Local Self-Hosted Distill Fallback (Ollama / OCI 24GB ARM): For 100% offline privacy or zero-rate-limit batch jobs, run
ollama run deepseek-r1:14b(Distill-Qwen-14B) on an Oracle Cloud Always Free 24 GB RAM ARM VM at $0.00/month forever.
3. DeepSeek Automatic KV Disk Context Caching ($0.014 / 1M Tokens) & Off-Peak Arbitrage
When scaling beyond free registration vouchers onto native api.deepseek.com billing, DeepSeek's Multi-head Latent Attention (MLA) and distributed disk KV-cache architecture deliver the lowest commercial token rates in the AI industry—without requiring manual cache-control headers:
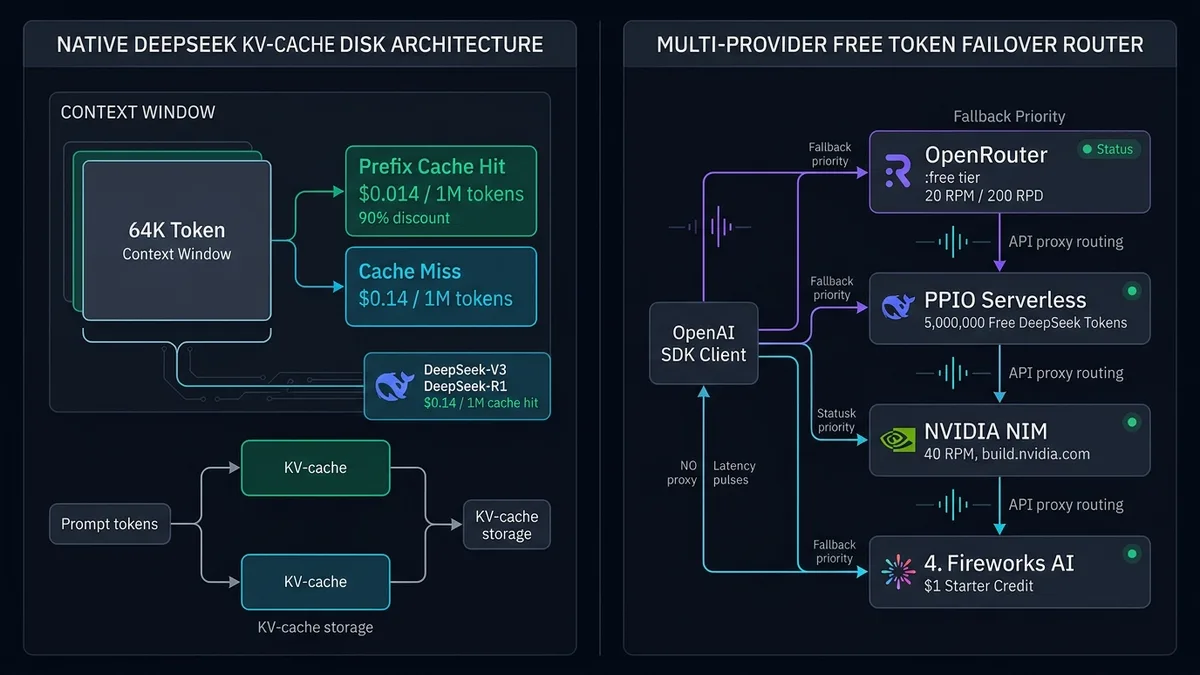
- Automatic 90% Prefix Cache Hit Discount: Any repeated system prompt, repository codebase map, or multi-turn conversation prefix (>= 64 tokens) is automatically served from distributed NVMe disk cache at $0.014 per 1M input tokens on DeepSeek-V3 (down from $0.14/1M on cache miss) and $0.14 per 1M input tokens on DeepSeek-R1 (down from $0.55/1M on cache miss).
- 50%–75% Off-Peak UTC Window (16:30–00:30 UTC): Native DeepSeek API endpoints apply automatic off-peak discounts during Beijing nighttime hours (16:30 to 00:30 UTC daily, corresponding to US daytime business hours: 11:30 AM to 7:30 PM EST), slashing DeepSeek-V3 by 50% and DeepSeek-R1 by 75%.
- Reasoning Token Accounting (
reasoning_content): Ondeepseek-reasoner(R1), internal Chain-of-Thought (CoT) tokens returned in thereasoning_contentfield are billed at the output token rate ($2.19/1M standard) but are automatically stripped from subsequent multi-turn input context to prevent quadratic context inflation.
4. Related Free LLM API Gateways & Agentic IDE Guides
Pair your DeepSeek-V3 and R1 endpoints with complementary zero-cost inference routers and developer IDEs:
Complete catalog of 15+ `:free` endpoints including DeepSeek-R1, Llama 3.3 70B, and Qwen 2.5 72B.
560 Tok/s LPU API GroqCloud Free Tier (30 RPM) →Ultra-low latency LPU inference on DeepSeek-R1-Distill-Llama-70B and Llama 3.3 70B at 30 RPM free.
1M Context Free Tier Google AI Studio Gemini Quotas →Route massive 1M-token repository context windows to Gemini 2.0 Flash for free (15 RPM, 1,500 RPD).
15–30 RPM Quota Matrix Gemini API Free Limits →Verified rate limits, 1M–4M TPM throughput, and daily reset mechanics across Gemini 2.0 Flash & Lite.
24GB ARM Always Free Oracle Cloud Free Tier ($300 + ARM) →Self-host quantized DeepSeek-R1-Distill-Qwen-14B via Ollama on 4 Ampere A1 ARM OCPUs & 24 GB RAM forever.
GitHub Migration GitHub Models Alternatives →Replace retired GitHub Models with cardless drop-in OpenAI SDK endpoints across OpenRouter, Groq, and DeepSeek.
Agentic Context Caching Antigravity IDE Token Matrix →Model prompt caching hit ratios and multi-agent token burn across Cursor, Cline, and Antigravity.
5. Frequently Asked Questions: DeepSeek API Free Credits & Quotas
Does DeepSeek still give 10 million free API tokens on signup in 2026?
DeepSeek's native platform (platform.deepseek.com) periodically issues ¥10 CNY (~5M to 10M tokens) onboarding grants to verified developer accounts, though direct registration grants can be temporarily paused during high-demand compute periods. Developers seeking guaranteed immediate free tokens with zero credit card can use OpenRouter's deepseek/deepseek-r1:free endpoint (20 RPM / 200 RPD) or claim PPIO's 5,000,000 token registration voucher.
How do I use DeepSeek-R1 and DeepSeek-V3 for free in Cursor or VS Code?
In Cursor, Continue.dev, or Cline/Roo Code, set your OpenAI Base URL to https://openrouter.ai/api/v1, paste your free OpenRouter API key, and add the model ID deepseek/deepseek-r1:free or deepseek/deepseek-chat:free. All completions route through OpenRouter's free community cluster at $0.00.
What is the difference between deepseek-chat and deepseek-reasoner in the API?
The model ID deepseek-chat points to DeepSeek-V3 (optimized for fast coding, tool calling, and structured JSON output at $0.014/1M cached input), whereas deepseek-reasoner points to DeepSeek-R1 (which generates internal Chain-of-Thought reasoning tokens in reasoning_content before outputting the final answer for complex math, algorithms, and debugging).
Are there rate limits on the native DeepSeek API?
Unlike traditional providers that enforce rigid Requests Per Minute (RPM) or Tokens Per Minute (TPM) ceilings, native api.deepseek.com endpoints do not impose fixed rate limits; instead, they dynamically manage concurrency based on real-time cluster load, keeping connections open via empty SSE keep-alive lines for up to 30 minutes before timeout.